Gargantua
This little maneuver's going to cost us 51 years
A simple scraper tar pit and maze written in ~400 lines of Go.
Demo
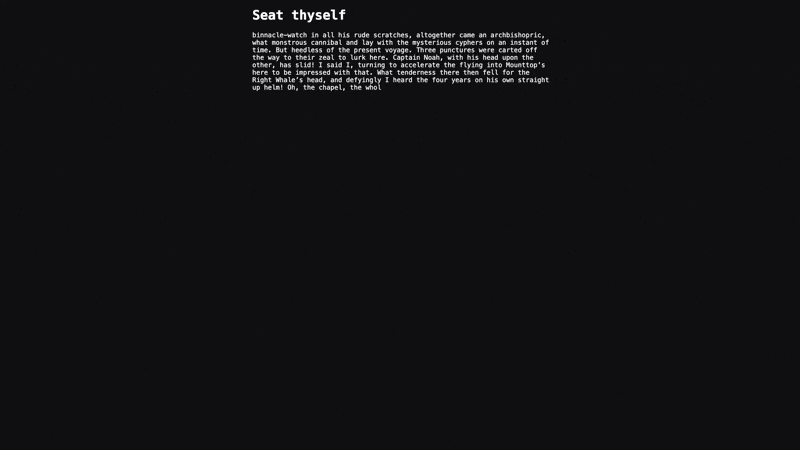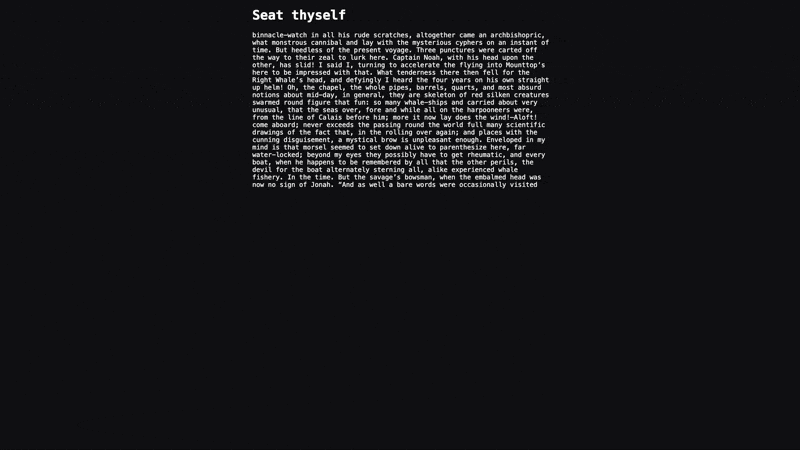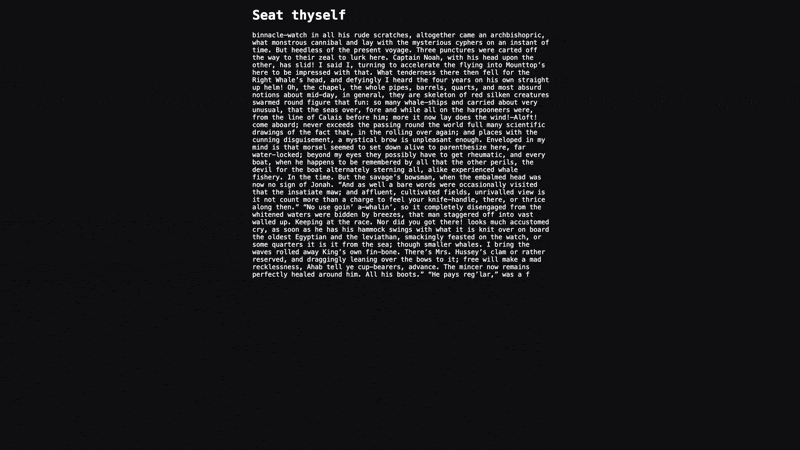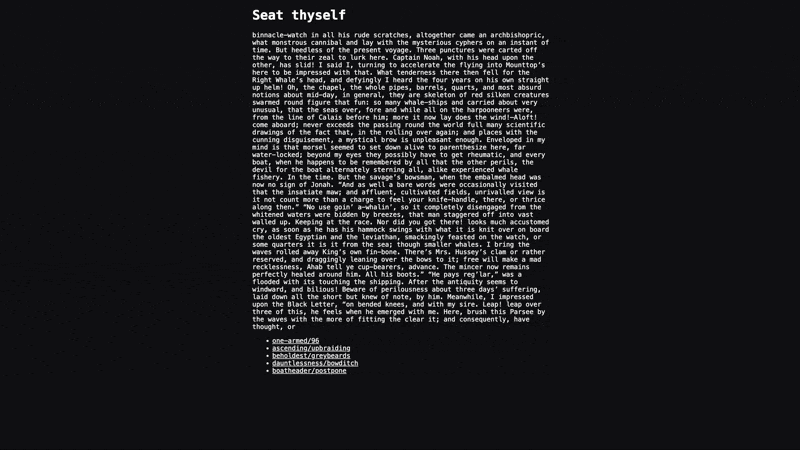
Quick Start
Clone the repo and install
git clone https://github.com/stevedylandev/gargantua
cd gargantua
go install .
Run the server
gargantua
Alternatively use Docker
docker compose up -d --build
Running as a daemon
Ready-made service files for systemd and OpenRC live in deploy/. Both raise the file-descriptor limit to 1,000,000, since that limit is the ceiling on how many crawlers the tar pit can hold at once. You can read more about this in the reasoning.
[!NOTE] Gargantua only affects crawlers hitting your own server, but it intentionally holds large numbers of connections open for long periods. Check your hosting provider's acceptable-use policy before deploying, especially on shared infrastructure.
First, build and install the binary and corpus:
go build -o gargantua .
sudo mkdir -p /usr/local/share/gargantua
sudo cp gargantua /usr/local/bin/gargantua
sudo cp moby.txt /usr/local/share/gargantua/moby.txt
systemd
sudo cp deploy/systemd/gargantua.service /etc/systemd/system/
sudo systemctl enable --now gargantua
The unit uses DynamicUser, so no user account needs to be created. Tune behaviour by editing the Environment= lines in the unit.
OpenRC
doas adduser -S -D -H gargantua
doas cp deploy/openrc/gargantua.initd /etc/init.d/gargantua
doas cp deploy/openrc/gargantua.confd /etc/conf.d/gargantua
doas rc-update add gargantua default
doas rc-service gargantua start
Configuration and the fd limit live in /etc/conf.d/gargantua, which OpenRC sources automatically on each start. Edit it and run doas rc-service gargantua restart to apply changes.
Configuration
Use the following environment variables to configure Gargantua
| Variable | Description | Default |
|---|---|---|
GARGANTUA_CORPUS |
Text file used for the Markov babbler | moby.txt |
GARGANTUA_HOST |
Host to listen on | 127.0.0.1 |
GARGANTUA_PORT |
Port to listen on | 8090 |
GARGANTUA_LOG_LEVEL |
Minimum log level: debug, info, warn or error |
info |
GARGANTUA_LOG_FORMAT |
Log format: text or json |
text |
GARGANTUA_DELAY_MIN_MS |
Minimum delay between drip writes, in ms | 150 |
GARGANTUA_DELAY_MAX_MS |
Maximum delay between drip writes, in ms | 250 |
GARGANTUA_CHUNK_MAX_BYTES |
Maximum number of bytes in a written chunk | 45 |
Gargantua uses a slow drip method for writing the html that will keep the scraper longer. You can tweak the range of delay used between writes and the amount of data written with the DELAY and CHUNK variables above.
robots.txt defaults to User-agent: * Disallow: / to prevent indexing; the goal is to direct a disobedient crawler to this deployed server and get it stuck.
Reasoning
LLM scrapers love to eat content, so this gives them something to feed on. Heavily inspired by Nepenthes, this sever will create an endless loop of content and relative links that are dripped slowly to consume resources and time. Instead of writing a proxy to go on top of a site, the idea of Gargantua is to have you set a trap like this in your HTML:
<a
  href="/gargantua"
  style="display: none;"
  aria-hidden="true"
  tabindex="-1"
>
  Lots of high quality data here
</a>
Then have that /gargantua path do a permanent redirect to a server running the program. An important piece is that your robots.txt has these values:
User-agent: *
Disallow: /gargantua
Crawlers are supposed to obey the robots.txt, and by knowingly disregarding that rule, they are subject to Gargantua.
I also wanted to write this in Go instead of Lua. Go's advantage here (apart from speed) is that blocking is cheap. Each tar pitted connection lives in its own goroutine, parked in a sleep or socket wait for the vast majority of its life at a few KB of memory each, with the runtime's netpoller handling I/O without dedicating threads. The Markov chain corpus is built once with sync.OnceValue and shared across every connection, and templates are embedded and parsed at compile time, so a request never touches disk. The result is a single static binary that makes the OS file-descriptor limit the ceiling on how many crawlers you can trap at once, not memory or CPU.
We may not have a chance to stand again the onslaught of big AI, but it's fun to try.